Data Quality Assurance
Reliable Data as the Foundation for Data-Driven Decisions
The Information Lab supports organisations in establishing structured, automated data quality controls. Our methodology encompasses explicit data quality rules, automated tests embedded within ELT pipelines, transparent transformations, and robust data models engineered to satisfy complex operational demands.
Data You Can Trust
An executive dashboard is only as dependable as its underlying data foundation. Inconsistent data formats, missing values, ambiguous definitions, or flawed calculations frequently originate long before data reaches the visual layer, silently distorting key performance metrics. Data quality must be safeguarded systematically during ingestion, transformation, and delivery.
The Information Lab implements automated quality assertions directly within ELT and data pipeline workflows. This architecture isolates data anomalies, logical flaws, and schema violations before they propagate into management reports or data products. Operating strictly tool-agnostic, we align testing frameworks with your existing technology stack. For scalable, version-controlled transformations, we frequently leverage frameworks like dbt when aligned with your architecture and operational use cases.
Data Quality with The Information Lab
The Information Lab combines specialised data engineering capability with a deep understanding of Business Intelligence, visual analytics, and functional business needs. We evaluate data quality not merely as a backend technical requirement, but through the eyes of the decision-makers who rely on that data daily.
While traditional data quality initiatives start exclusively in the backend, we complement this by evaluating the exact data models, metric definitions, and schemas required for intuitive, high-performance analytics. Our extensive background in dashboard engineering, executive reporting, and visual analytics informs the design of data models, automated test suites, and quality rules.
Core Pillars of Data Quality
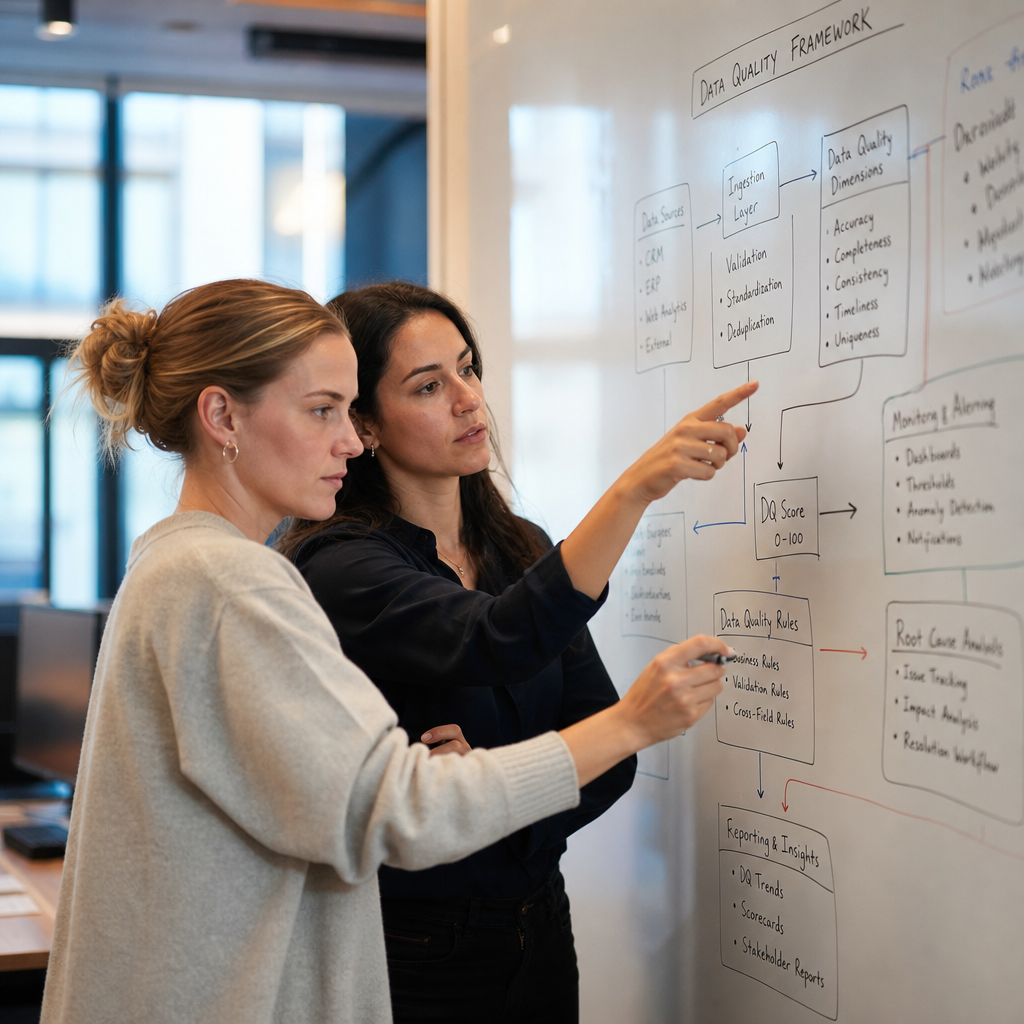
Sustainable data quality is built through explicit rules, resilient data models, transparent transformation logic, and automated tests embedded directly within data pipelines. End-of-pipeline validation checks are insufficient for enterprise operations.
By embedding governance into ingestion pipelines, data models, and reporting structures, quality remains verified, transparent, and manageable throughout live operations.
- Valid Data Models
Dimensional schemas accurately reflect real-world business logic, delivering consistent, reliable metrics across all business units. - Automated Pipeline Testing
In-pipeline testing protocols detect structural and logical anomalies early, allowing controlled remediation prior to report publishing.. - Explicit Quality Rules
Business definitions, valid ranges, mandatory fields, and logic assertions establish a clear baseline for what constitutes verified data. - Executive Trust in Analytics
When data quality is systematically guaranteed, business units adopt dashboards and analytics with total confidence.
Case Study: Eliminating Metric Distortion
During a global dashboard deployment for a corporate group, The Information Lab engineered an end-to-end data pipeline and visual analytics suite. Internal stakeholders initially hesitated to adopt new reports due to past experiences where opaque calculation logic delivered inaccurate figures.
A primary driver of error was the historical aggregation of mixed financial currencies (USD and EUR) without a unified exchange rate framework. We resolved this through precise dimensional modeling: financial transactions are now maintained with explicit currency attributes, standardised automatically into Euros, and aggregated exclusively via the validated Euro metric column.
In the ELT pipeline, automated dbt tests verify that every transactional amount possesses a valid currency code and a corresponding exchange rate prior to model compilation. This prevents calculation errors from recurring or spreading into downstream analytics models. The visual dashboard suite gained a verified data foundation and was adopted across executive leadership with complete trust.
Our Quality
Assurance Framework

Audit Current State
We evaluate existing source systems, ELT pipelines, transformation logic, data models, and dashboards to isolate quality risks that impact decision-making.
Define Quality Rules
Collaborating with business stakeholders, data teams, and IT leads, we establish explicit data quality rules, covering technical assertions, business logic, metric definitions, completeness, and freshness.
Automate Pipeline Testing
We embed quality assertions directly into automated data pipelines. Anomalies and schema breaks are flagged, documented, and isolated instantly.
.
Stabilise Data Models
We refactor data models and transformation logic to ensure they mirror complex business requirements accurately while remaining maintainable long-term.
Enable Internal Teams
Data quality remains stable when teams understand how rules, tests, and data models interlock. We deliver documentation, structured enablement, and hands-on coaching.
Data Quality for BI, Analytics, and AI Applications
Dependable data is not only vital for executive dashboards; AI applications, predictive forecasting engines, process automation, and self-service BI also depend on an audited data layer.
As data landscapes expand in complexity, explicit validation rules, semantic structures, and transparent data lineage become paramount. Verified data quality provides the essential foundation for sound analytics, trusted AI models, and scalable enterprise data products.
Project-Based Delivery
with Managed Data Teams
When internal engineering teams require extra delivery capacity or specialised technical knowledge, our Managed Data Teams provide immediate operational reinforcement. Led by experienced Senior Consultants, our consultants establish data quality rules, engineer automated pipeline tests, stabilise dimensional data models, and refactor existing ingestion pipelines. We advance your data quality roadmap while keeping technical knowledge anchored within your organisation.
Trust Through Security and Certified Standards
Data quality is intrinsically linked to information security, complete traceability, and strict engineering standards. The Information Lab is ISO 27001 certified, serving clients where confidentiality, data integrity, and audited processes are paramount.
Our senior consultants bring deep experience across BI, analytics, data engineering, and cloud platforms, operating across technologies such as dbt, Snowflake, Tableau, and Microsoft Power BI. Remaining tool-agnostic, we align quality frameworks strictly with your existing IT architecture. Independent client reviews on ProvenExpert confirm our execution quality, where over 900 client testimonials maintain an average rating of 4.8 out of 5 stars.
Trainings & Webinare
Data quality remains high only when internal teams understand how quality rules, dimensional models, and automated pipeline tests interlock. Our practical training formats instruct teams on engineering, monitoring, and maintaining data quality across pipelines, transformation layers, and analytics environments.
Expert Knowledge
Establish Data Quality Across Your Ecosystem
Data quality can be systematically improved once you identify where anomalies occur, which metrics are business-critical, and which pipeline tests can be automated.
An initial audit of your active data pipelines, data models, and executive dashboards will quickly surface high-priority action areas and demonstrate how automated testing builds trust in business analytics.
Benjamin Gretsch
Lead Data Engineer
Startseite- & Serviceskontakformular ENG
"*" indicates required fields
Frequently Asked Questions
Why do modern BI tools frequently display inconsistent or conflicting metrics?
Visual analytics tools like Tableau or Microsoft Power BI render the data delivered by underlying backend systems. When dashboards show conflicting figures, the issue almost always stems from upstream data preparation. Omitted currency conversions, ambiguous business definitions, or inconsistent formats across source applications lead to distorted results. Structured data quality assurance addresses these errors upstream, resolving inaccuracies before they reach executive reports.
How are quality assertions automated within data pipelines?
Manual data validation using intermediate spreadsheet exports is slow, inefficient, and error-prone. The Information Lab shifts quality control directly into the ELT pipeline. Utilising frameworks like dbt, we configure automated tests that evaluate every pipeline run for missing values, boundary violations, or schema drift. Invalid records are isolated immediately, drastically increasing the reliability of your Data Warehouse (e.g. in Snowflake).
What operational advantage does your visual analytics perspective bring to data quality?
Traditional IT service providers often treat data quality strictly as a backend technical task. The Information Lab approaches data quality with extensive visual analytics experience, understanding precisely how data must be modeled for business departments to query it rapidly and intuitively. This visual analytics background informs our backend data models and testing suites, ensuring technical engineering serves clear business outcomes.
What role does data quality play in Artificial Intelligence initiatives?
While poor data quality is frustrating in traditional reporting, it is fatal to AI initiatives. Machine Learning algorithms and GenAI models learn from the data provided to them. Flawed, incomplete, or biased raw inputs inevitably produce inaccurate predictions or model hallucinations. An audited, fully traceable data foundation is an absolute prerequisite for deploying Artificial Intelligence safely and effectively.
How is information security guaranteed during data quality engagements?
Auditing and cleansing business data requires access to business-critical systems. As an ISO 27001 certified partner, The Information Lab enforces strict information security protocols. From our headquarters in Hamburg, our consultants manage data environments for corporate groups and mid-market leaders across Germany, Austria, and Switzerland (DACH), including heavily regulated sectors such as financial services and pharmaceuticals where data integrity and confidentiality are mandatory.
