ETL & ELT Consulting
Ingest, Transform, and Activate Business Data
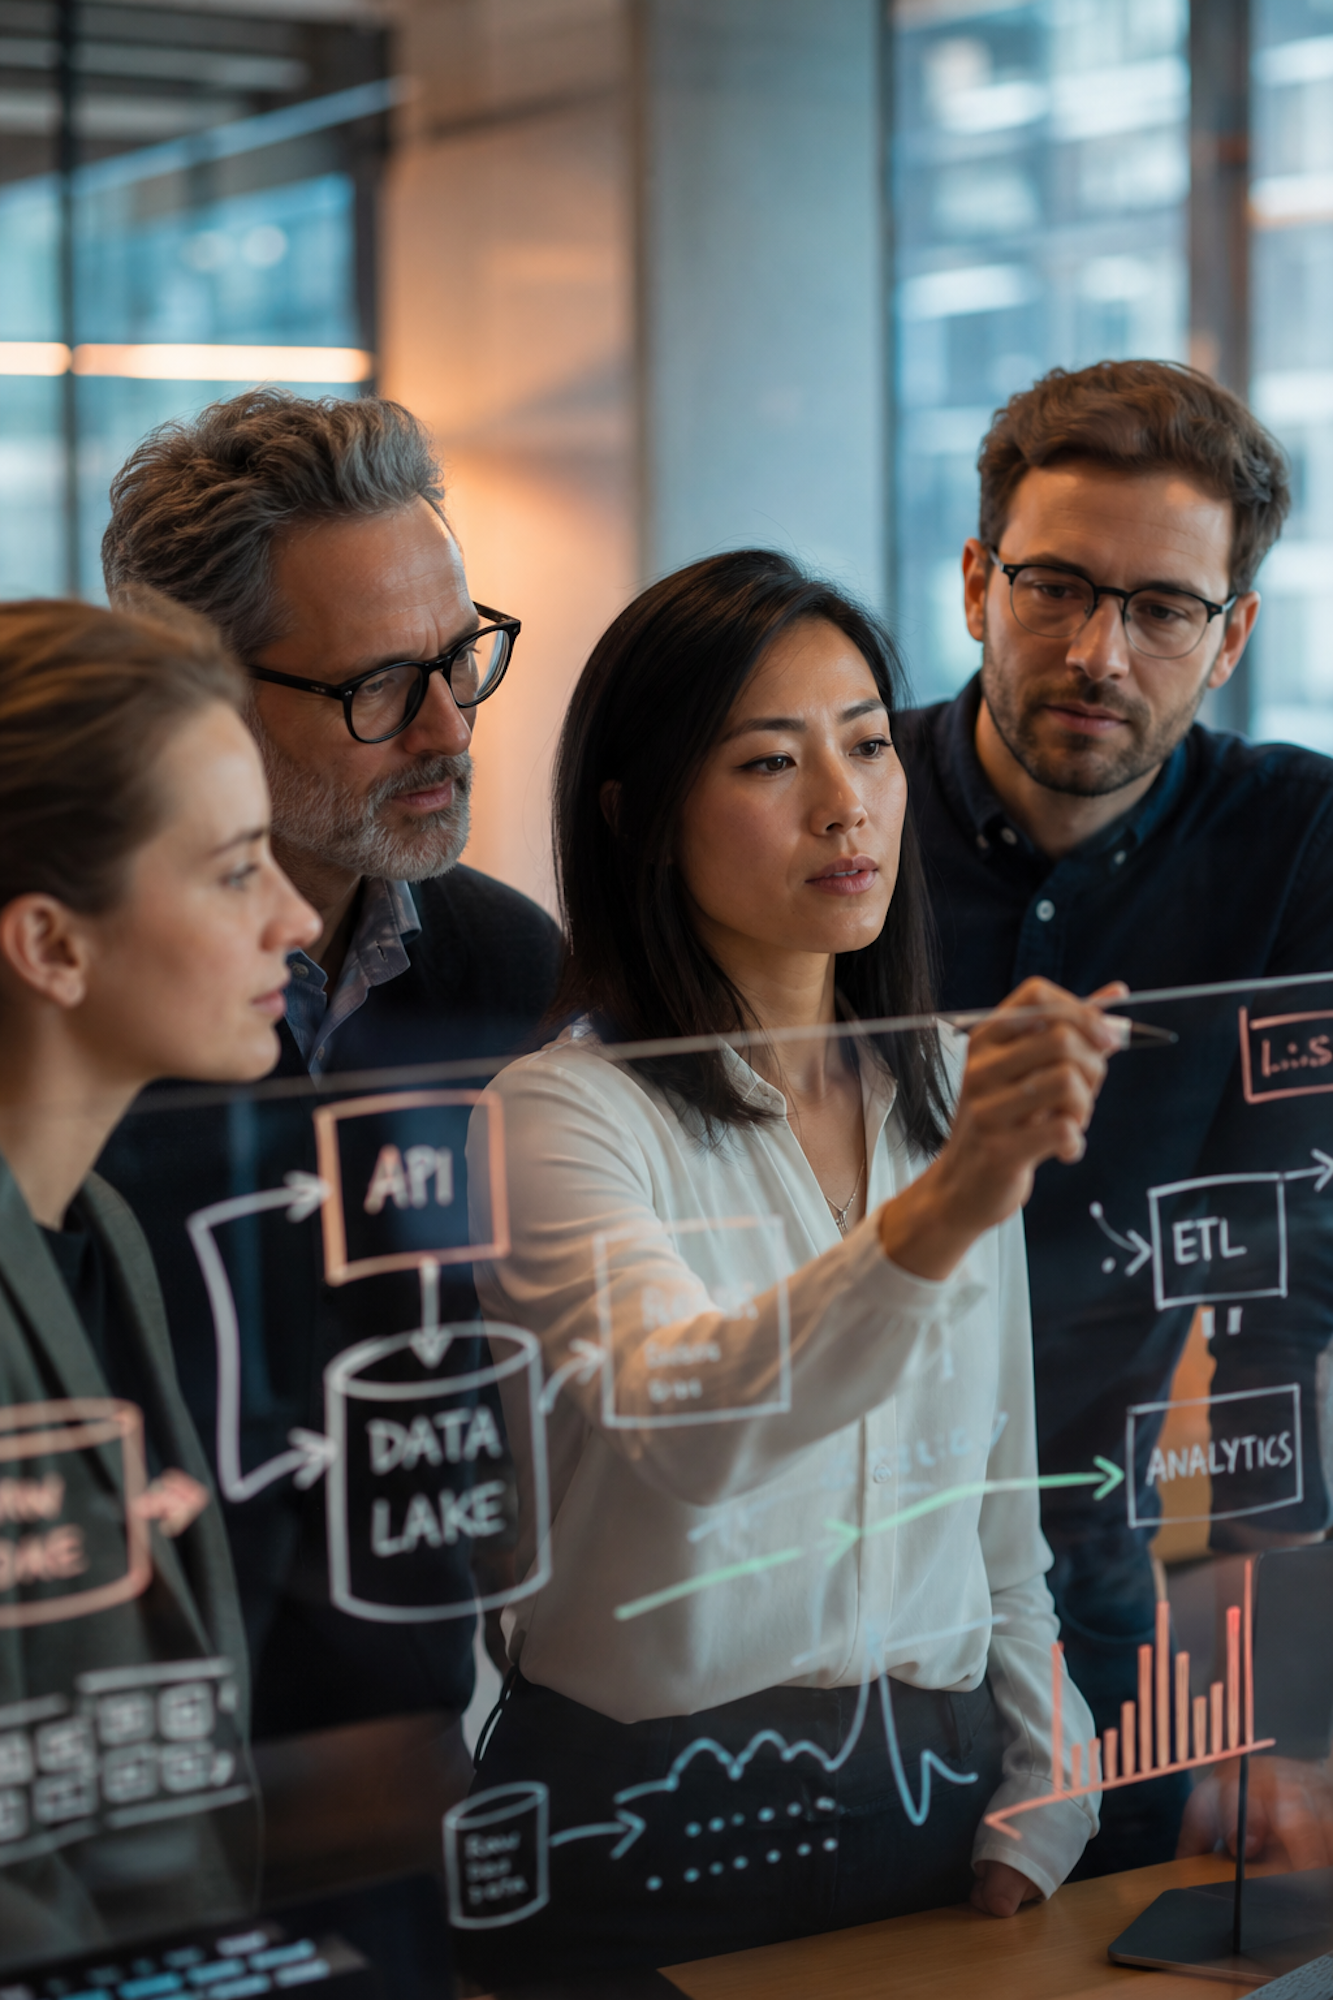
The Information Lab supports enterprise clients in designing, modernising, and scaling ETL and ELT data integration processes. We integrate data reliably from disparate source systems, transform it transparently, and convert raw inputs into performant, scalable data models. Depending on your data architecture, regulatory compliance mandates, and existing technology stack, we engineer modern ELT pipelines, classic ETL workflows, or hybrid integration solutions.
Why ETL and ELT Are Essential to Business Analytics
Data generates tangible business value only when it is reliably extracted from source systems, cleansed, validated, and structured for downstream consumption. Storage represents just one element of a depandable data architecture. ETL and ELT processes serve as the engine between source applications, data warehouses, analytics platforms, executive reports, and AI applications.
They ensure raw data is never isolated in operational silos, but systematically loaded, transformed, and delivered to power high-impact business use cases. Selecting the optimal approach depends on your data landscape, cloud strategy, compliance requirements, and operational use cases. While modern cloud architectures favor ELT, classic ETL workflows remain highly relevant in regulated or hybrid ecosystems.
End-to-End Capability Focus
The Information Lab designs data integration and transformation pipelines driven by downstream application. We engineer pipelines so data flows reliably on a technical level while providing intuitive, fast structures for interactive dashboards, advanced analytics, data products, and AI models.
Our deep operational background across BI, visual analytics, data engineering, data warehousing, and dashboard design directly informs our pipeline modeling. The resulting data structures accommodate complex business logic, remain technically stable, and simplify daily data usage across departments.
We assist in building greenfield data pipelines, modernising legacy ETL workflows, selecting optimal technology stacks, and embedding automated quality testing, technical documentation, and governance guardrails.
Delivering Value Through
Optimised Data Pipelines
How expert pipeline engineering transforms your data landscape into a scalable, enterprise-grade driver of growth.

High-Speed Dashboard & Report Performance
Pre-aggregated, dimensional data models engineered directly within your Data Warehouse eliminate dynamic frontend transformations. This guarantees sub-second query speeds, seamless dashboard interactions, and reliable performance at scale.
A Single Source of Truth Across Departments
Standardised ETL and ELT pipelines establish unified transformation logic across your entire enterprise. By eliminating metric discrepancies between teams, leadership gains a trusted, consistent foundation for strategic decision-making.
Automated Operational Workflows
Automating manual data transfers and spreadsheet workflows eliminates human error, guarantees data integrity, and restores full auditability—freeing internal teams to focus on high-value analytics.
Fully Transparent Data Lineage & Governance
Cleanly engineered pipelines make data flows, transformations, and dependencies completely transparent. Business users and auditors can effortlessly trace any KPI back to its original source with total confidence.
AI-Ready Data Foundations
Structured, semantically consistent, and continuously audited data pipelines create the robust infrastructure needed to power predictive models, agentic workflows, and enterprise AI applications reliably.
Our Integration Services
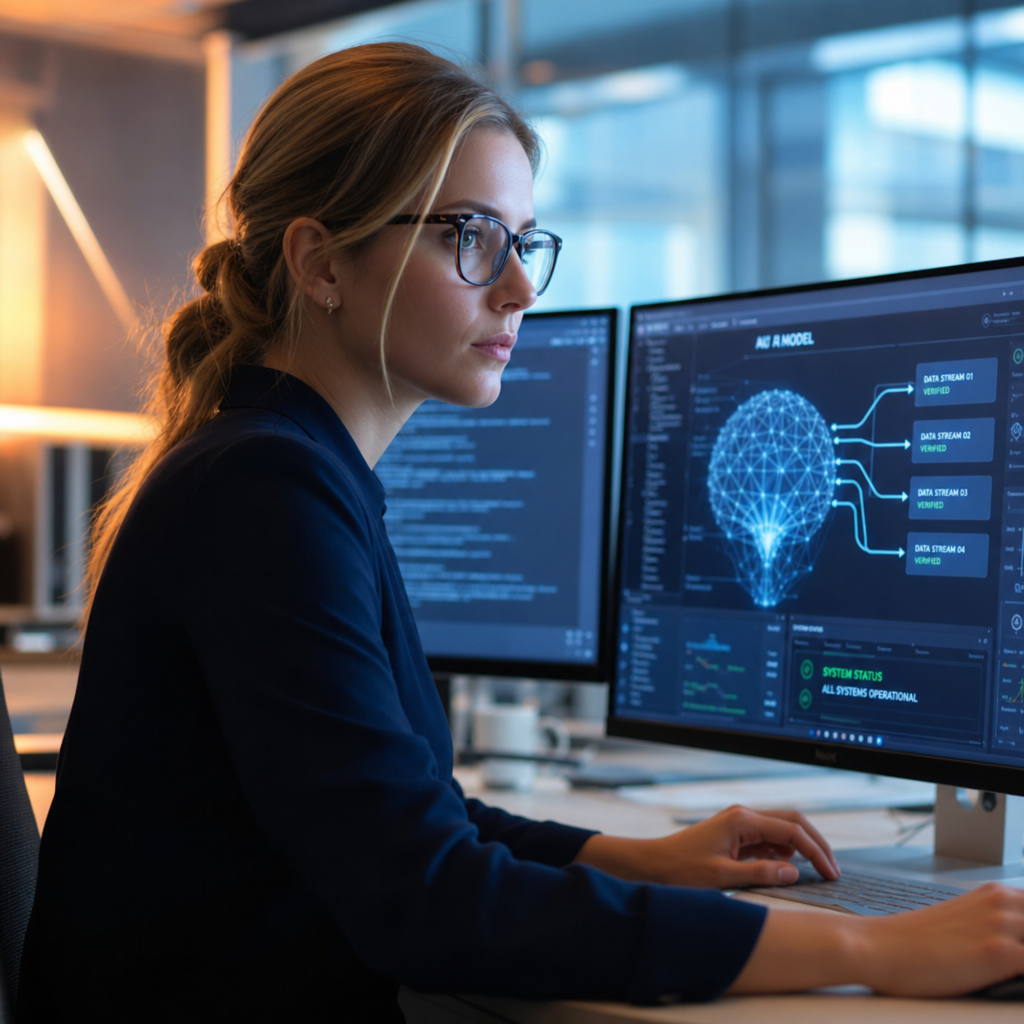
Engineering Pipelines for Warehousing & AI
ETL and ELT processes represent a core operational component of modern data architectures. Within Data Warehousing, they ensure data is loaded consistently and transformed efficiently. For Data Quality, they enable automated testing protocols, explicit validation rules, and transparent processing logs.
Similarly, Artificial Intelligence applications require available, well-structured, and contextually accurate data. Consequently, ETL and ELT pipelines act as the essential bridge across the entire Data Value Chain.

Project Delivery via
Managed Data Teams
When internal engineering teams require specialised technical knowledge or extra delivery capacity, our Managed Data Teams support the implementation, refactoring, and maintenance of your ETL/ELT pipelines. Our teams connect new source systems, engineer automated pipelines, build dbt transformation models, integrate testing frameworks, and stabilise existing integration workflows, delivering rapid progress without requiring full operational outsourcing.
Trust Through Experience & Partnerships
The Information Lab brings extensive project experience across data engineering, BI, visual analytics and cloud architectures for clients of varying digital maturity. Our engineers and consultants hold certified expertise across market-leading platforms, including Snowflake, dbt, Databricks, Microsoft SQL Server and Oracle.
As an official partner of Snowflake and dbt, we deliver deep expertise in modern cloud data platforms and analytics engineering methodologies. Furthermore, our ISO 27001 certification guarantees information security, audited operational processes, and strict data protection compliance. Independent client reviews on ProvenExpert confirm our execution quality, where over 900 testimonials maintain an average rating of 4.8 out of 5 stars.
Training & Enablement
Data pipelines remain stable over the long term only when internal engineering and analytics teams understand how integration, transformation, quality testing, and documentation interlock. Our role-based training formats provide practical instruction on building, testing, monitoring, and scaling modern data pipelines independently.
Insights
Knowledge Shared by Our Team
Contact our advisory team to evaluate your data integration Setup
Your choice of ETL and ELT architecture determines whether your data initiatives scale smoothly or remain trapped in manual, high-maintenance workflows. An initial review of your source applications, existing pipelines, data models, and reporting layers will rapidly surface bottlenecks and identify the optimal integration architecture.
Benjamin Gretsch
Lead Data Engineer
Startseite- & Serviceskontakformular ENG
"*" indicates required fields
Frequently Asked Questions
What is the core difference between ETL and ELT?
In classic ETL (Extract, Transform, Load), data is extracted from source systems, transformed on an external processing server, and then loaded into the target database. In modern ELT (Extract, Load, Transform), raw data is loaded directly into a cloud data warehouse or lakehouse first. Transformations are executed natively inside the target system, leveraging the elastic, parallel compute power of modern cloud platforms (such as Snowflake). ELT offers better scalability and flexibility for dynamic business demands.
When is a classic ETL process still recommended?
Despite the industry shift toward ELT, classic ETL workflows remain essential in specific scenarios. This is particularly true for on-premise IT infrastructures or heavily regulated environments (such as banking and insurance) where sensitive personal or financial data must be masked, anonymised, or filtered before being loaded into a central database repository.
How do structured data pipelines eliminate dashboard performance issues?
Severe query latency in platforms like Tableau or Microsoft Power BI typically occurs because complex calculations, historical aggregations, and multi-table joins are processed dynamically inside the frontend dashboard during user interaction. Well-engineered ETL/ELT pipelines shift this processing workload to the backend. The Data Warehouse delivers pre-aggregated, optimised dimensional data models directly to the reporting tool, dramatically accelerating query rendering.
Which technology stacks and tools are used to build data pipelines?
The Information Lab provides tool-agnostic advisory, selecting tools matched to your existing IT landscape. Typical modern setups combine scalable ingestion tools like Fivetran or Airbyte for data extraction with dbt (data build tool) for version-controlled, testable SQL transformations inside the Data Warehouse. For self-service analytics in business departments, visual tools like Alteryx or Tableau Prep are frequently integrated downstream.
Why are automated pipelines essential for Artificial Intelligence?
Machine Learning models and GenAI applications require reliable, clean, and fully documented data. Automated ETL/ELT pipelines ensure AI interfaces are fed continuously with high-quality, validated enterprise data. They prevent models from processing corrupted or incomplete raw inputs, eliminating the risk of unviable or biased outputs (Garbage In, Garbage Out).
Does The Information Lab offer long-term operational pipeline support?
Yes. When internal engineering capacity is constrained, The Information Lab provides ongoing operational maintenance and pipeline management. Through our Managed Data Teams model, experienced consultants assist in live operational environments, securing data quality, monitoring pipeline performance, and scaling existing integration processes. From our headquarters in Hamburg, we manage data infrastructures for corporate groups and mid-market leaders across Germany, Austria, and Switzerland (DACH).
